 Open Weights & Code LLMs
DeepSeek Launches V4.1-Flash: A Production Causal Encoder-Decoder, Native Vision, and a 4x Smaller KV Cache
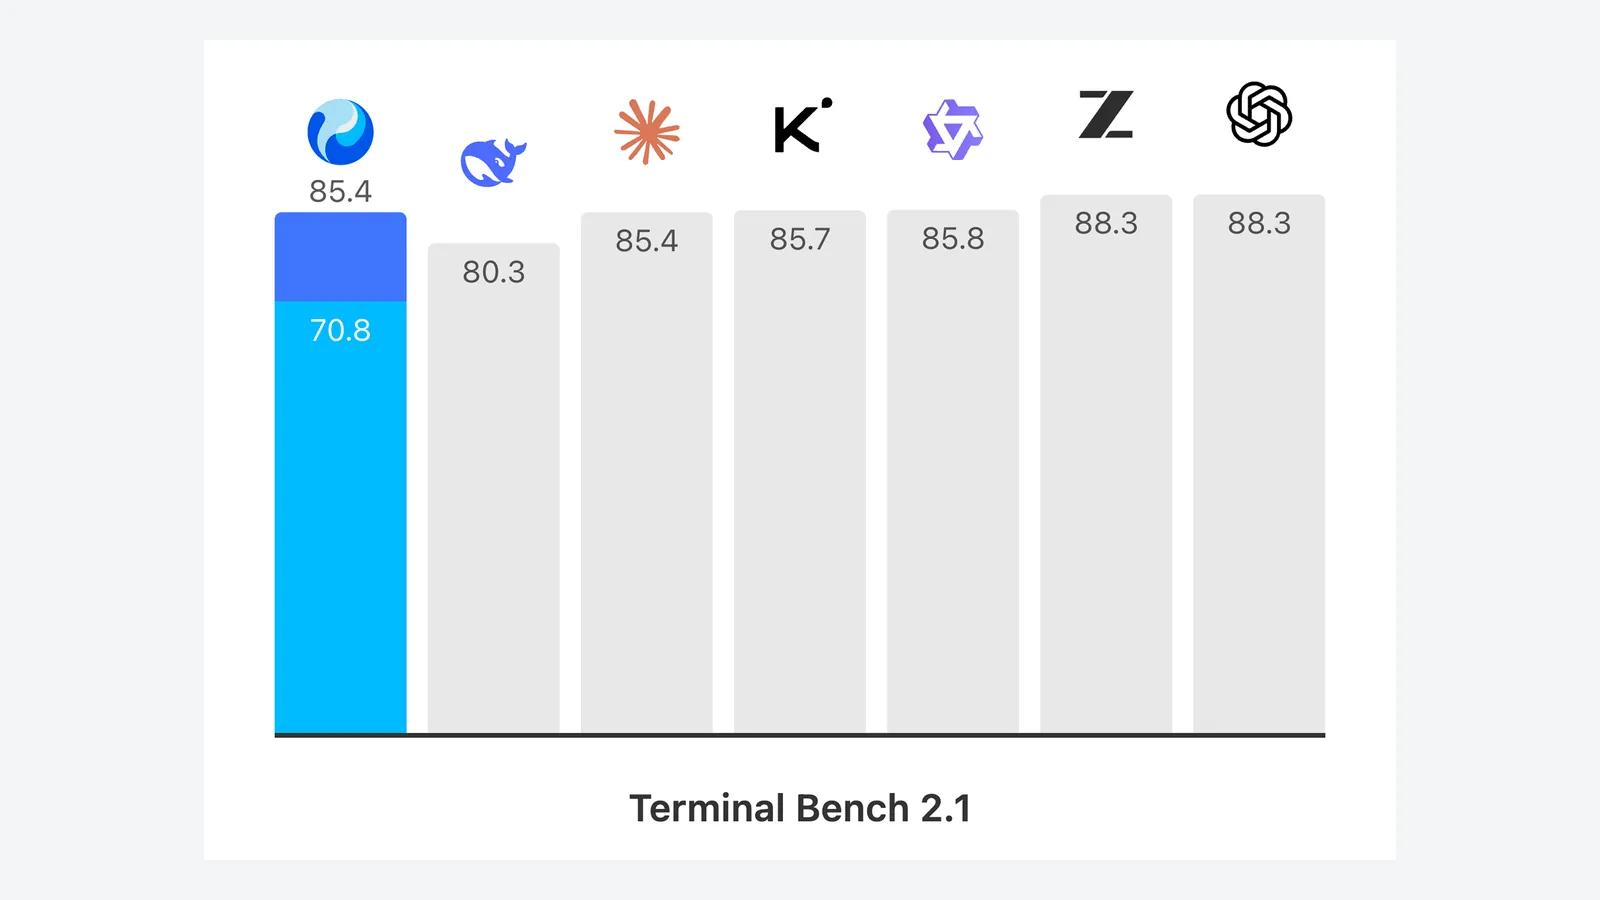
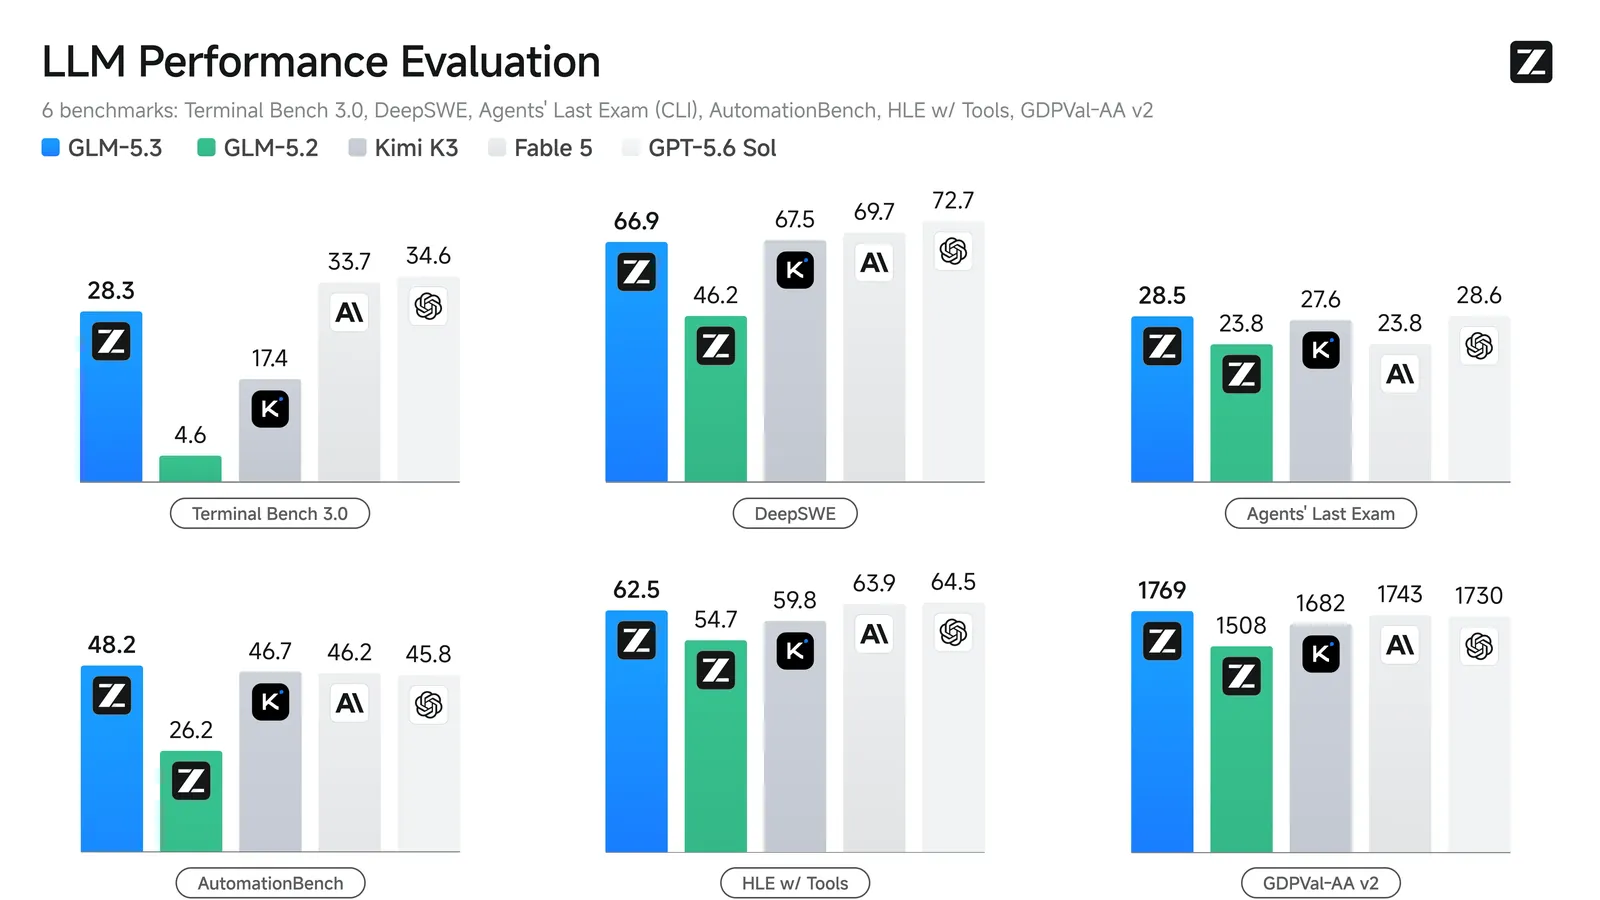
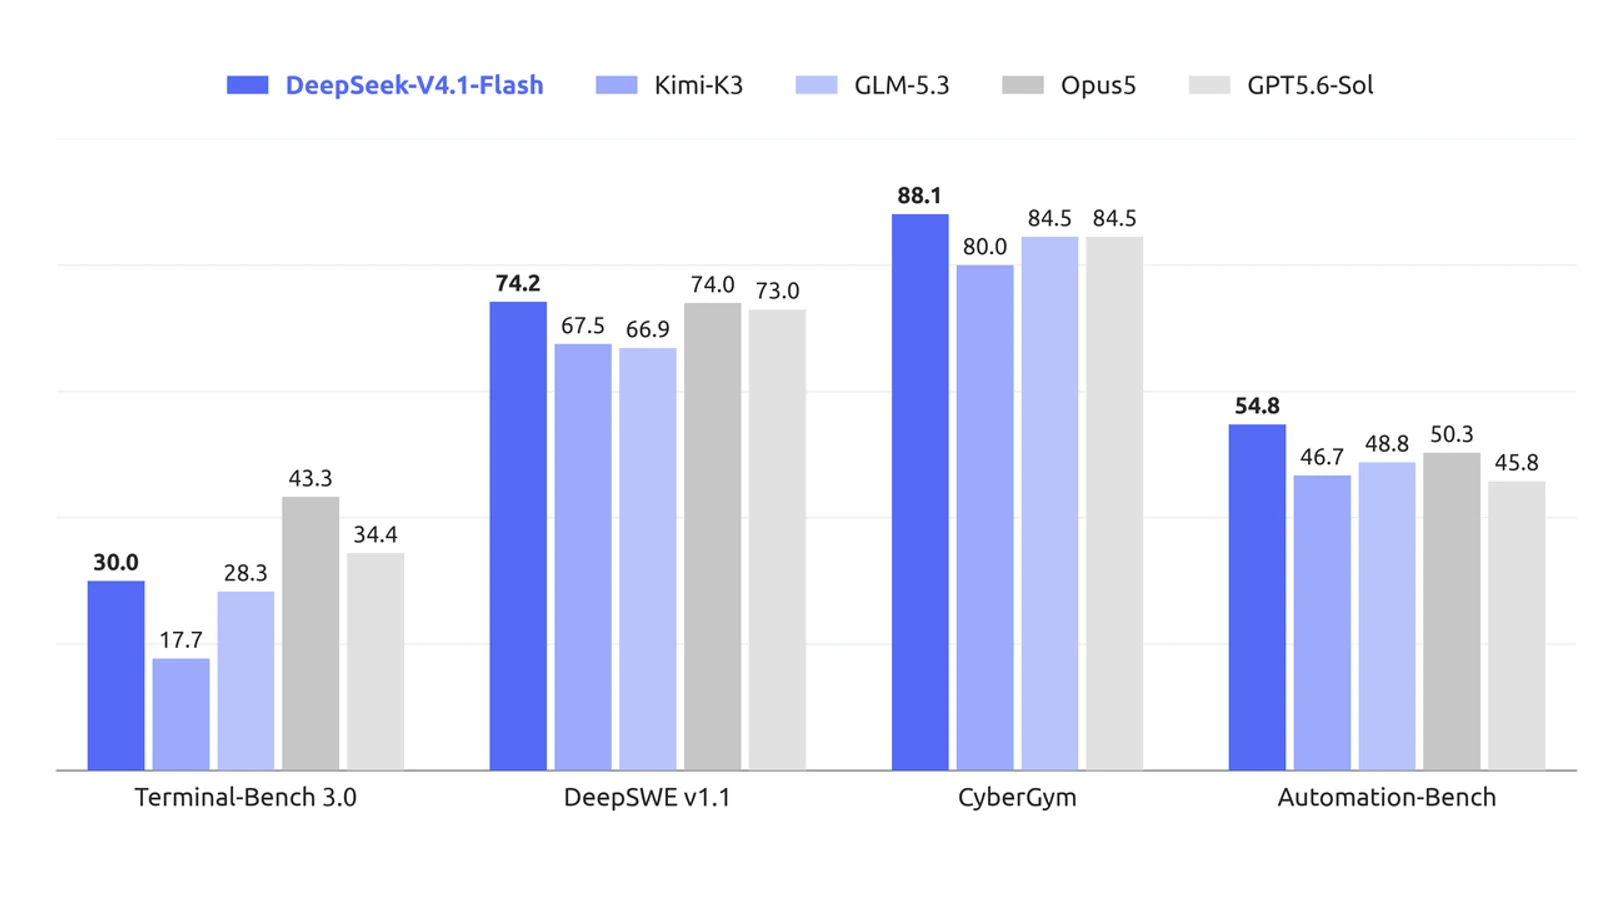
DeepSeek released V4.1-Flash today, the smallest model in its new architecture family: a 552B MoE built on a Causal Encoder-Decoder that activates 8B parameters for input and 16B for output, an 890-byte-per-token KV cache, vision trained in from the start, 1M-token context, and lower API pricing with a plan to route all V4-Pro traffic to it. Weights are open under MIT, and the official comparison table shows exactly where it leads Opus 5 and where it trails.